Bhuvan Sachdeva
I'm a Member of Technical Staff at Stellon Labs, where I work on text-to-speech (TTS) and automatic speech recognition (ASR) models. I joined in July 2026.
Previously, I was a research fellow at Sankara Eye Hospital and Microsoft Research India, where I worked with Dr. Mohit Jain, Dr. Vineeth N B, and Prof. Thomas Schultz.
My research spans speech, vision-language models, and healthcare AI. My previous work includes task-transfer dynamics in vision-language models, surgical scene understanding in cataract surgery, and expert-in-the-loop LLM chatbots for patients and community health workers.
I received my B.Tech. in Computer Science from Delhi Technological University (DTU) in 2023. During my undergrad, I interned at Prime Video, Amazon and Kroop AI.

News
- Sep 2026 BAGEL-RL: Low-Rank Reinforcement Learning for Interleaved Visual Reasoning accepted to Embodied Spatial Reasoning @ NeurIPS 2026!
- Sep 2026 Swift Sampling: Selecting Temporal Surprises via Taylor Series accepted to NeurIPS 2026!
- Sep 2026 Advancing automated phase recognition in cataract surgery through the SICS-155 challenge accepted to Medical Image Analysis!
- July 2026 Joined Stellon Labs as a Member of Technical Staff, working on text-to-speech (TTS) and automatic speech recognition (ASR) models.
- Feb 2026 Understanding Task Transfer in Vision-Language Models accepted to CVPR 2026 (Oral)!
- Sep 2025 Presented Phase-Informed Tool Segmentation for Manual Small-Incision Cataract Surgery at MICCAI 2025 and hosted the SICS-155 Phase Prediction Challenge.
- Sep 2025 Understanding Task Transfer in Vision-Language Models accepted to the Unireps Workshop @ NeurIPS 2025.
- June 2025 Phase-Informed Tool Segmentation for Manual Small-Incision Cataract Surgery accepted to MICCAI 2025!
Selected Papers (full list)
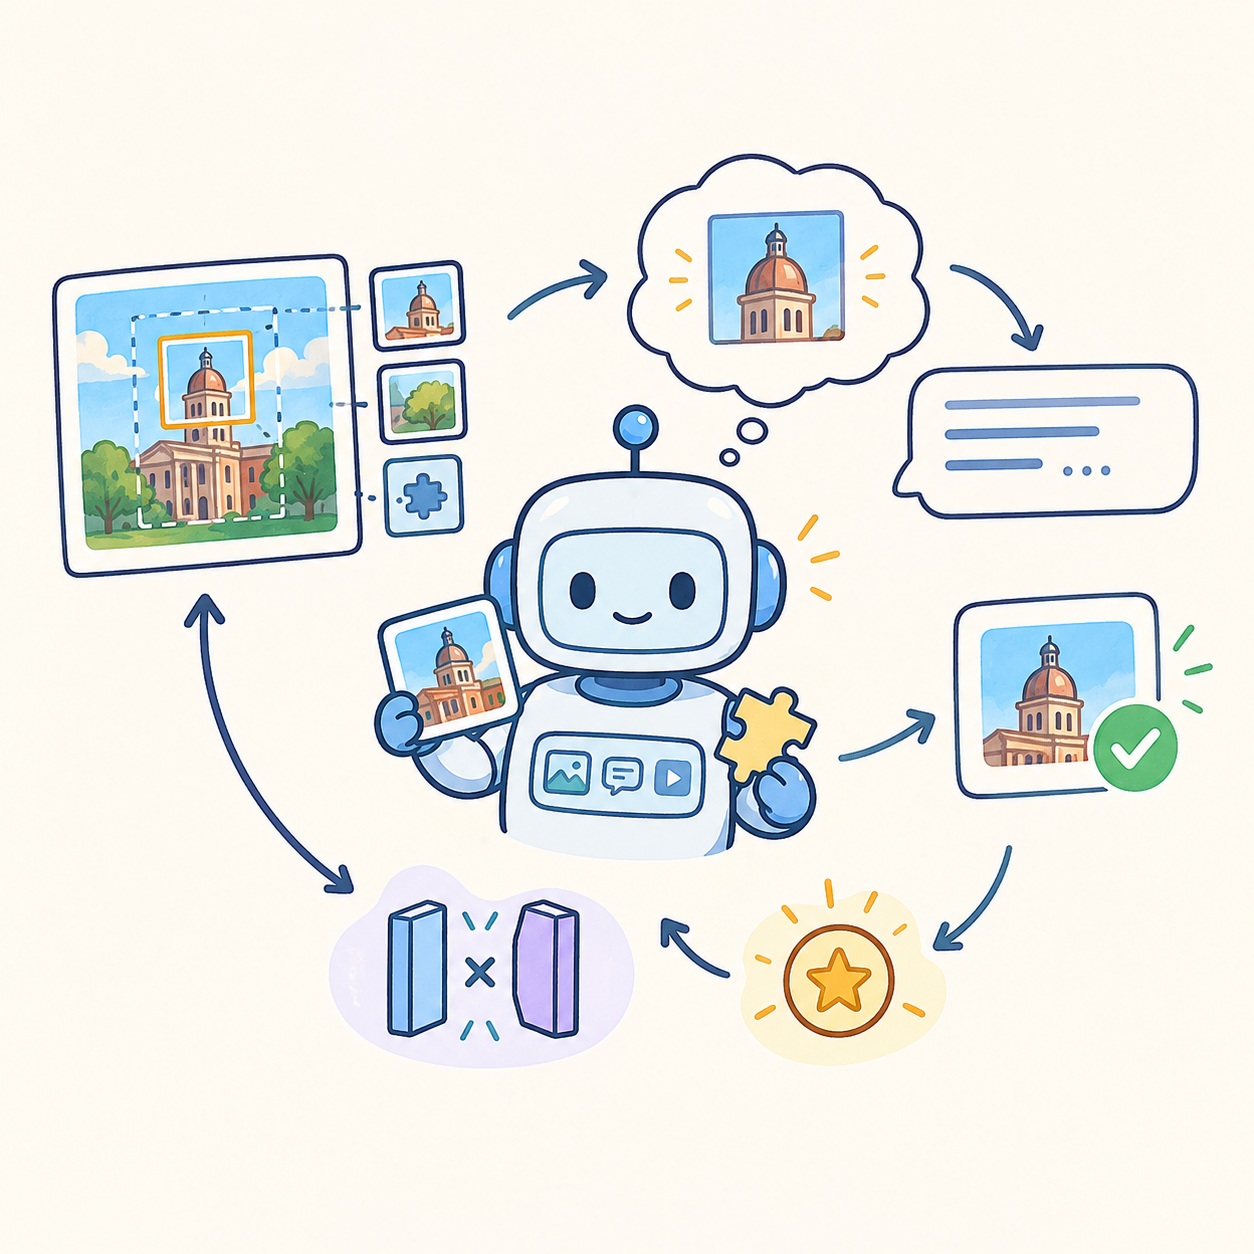
We introduce a parameter-efficient adaptation of BAGEL using Group Relative Policy Optimization (GRPO) with Low-Rank Adaptation (LoRA) for interleaved visual reasoning. BAGEL-RL improves average benchmark performance from 62.49% to 70.36% while updating only 2.6% of the model parameters.
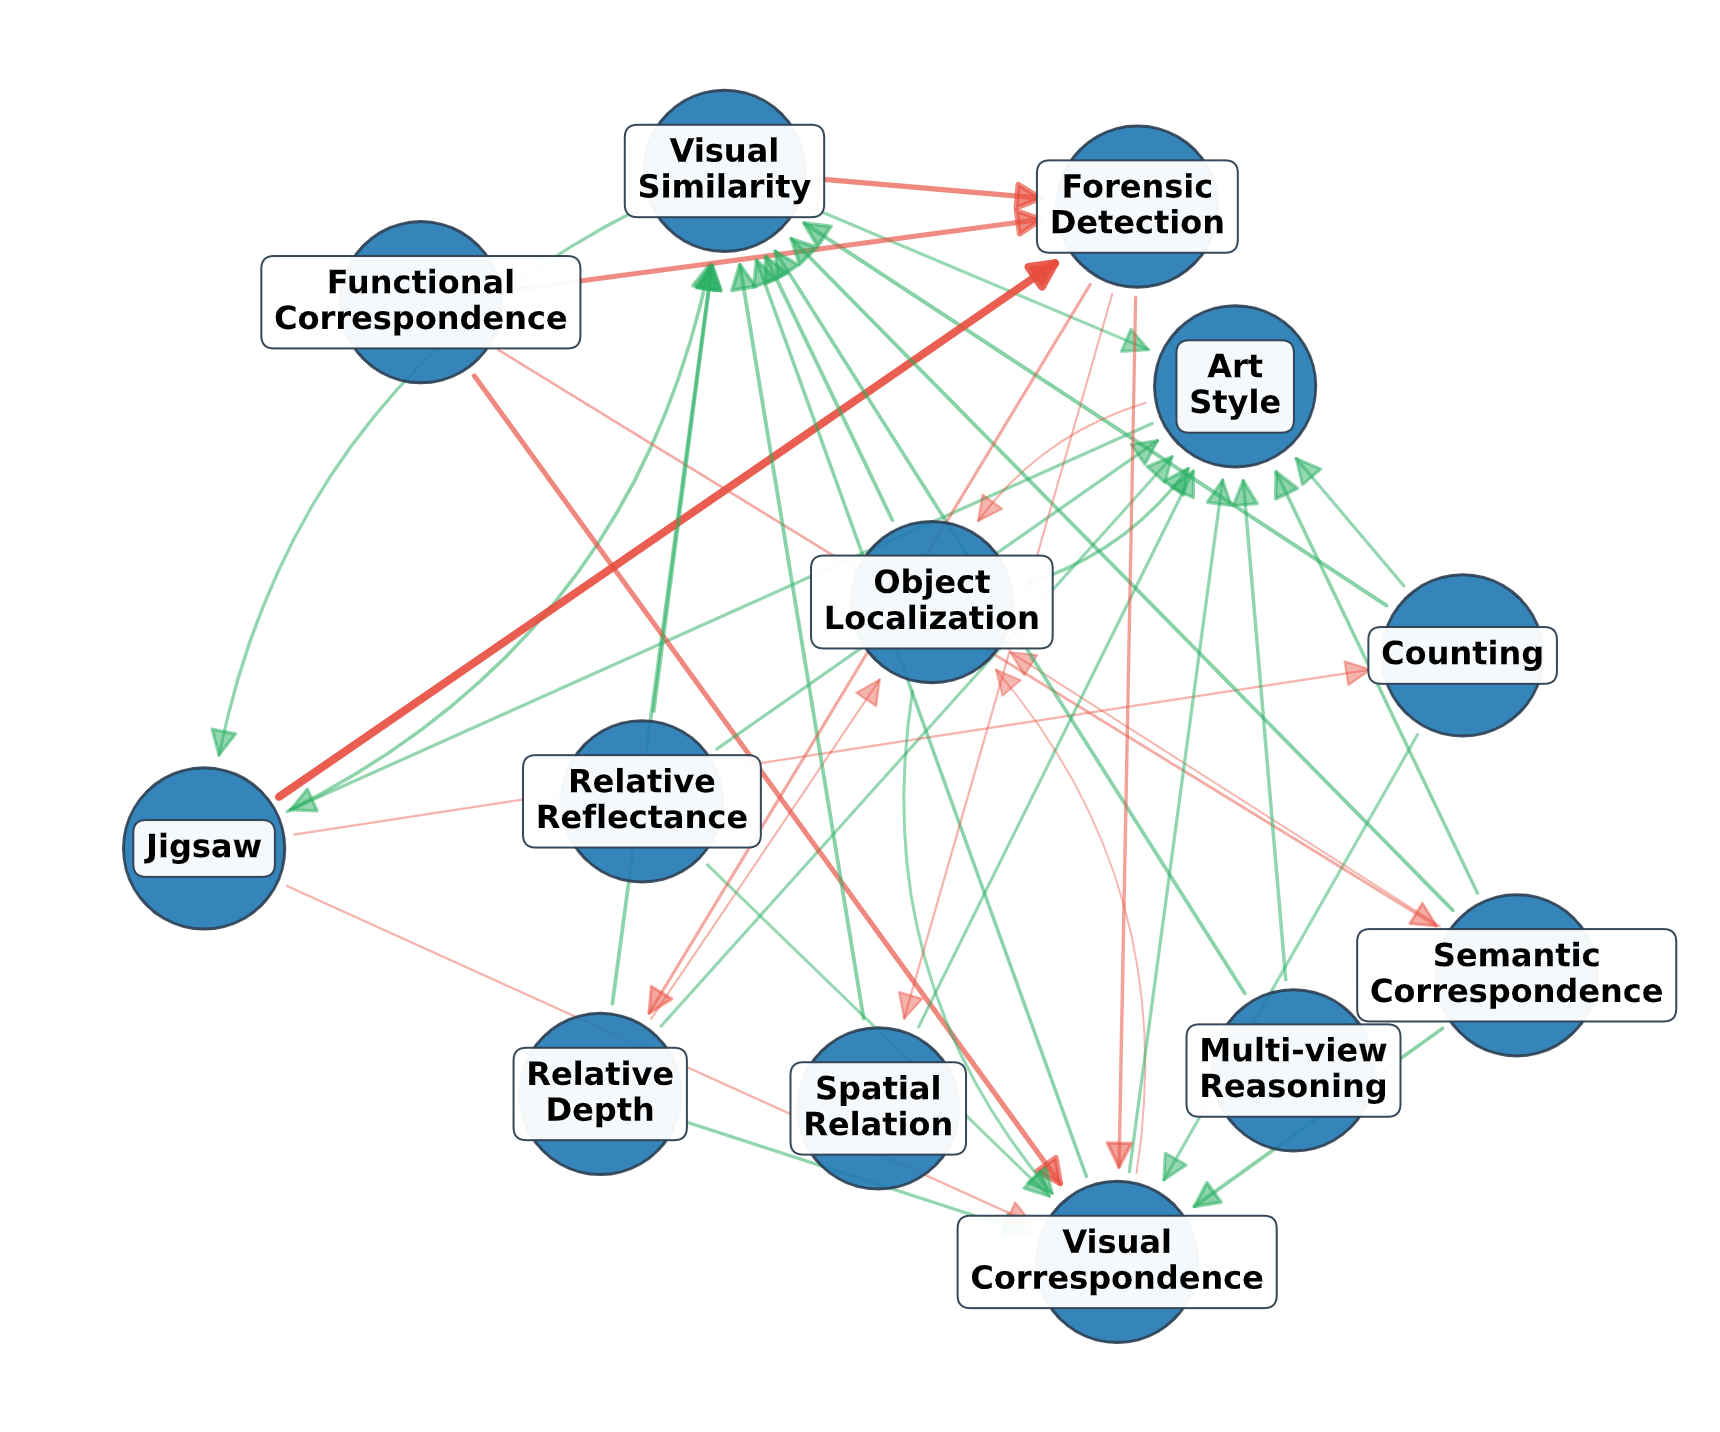
We investigate how finetuning on one task affects zero-shot performance on others across the Qwen-2.5-VL model family. We introduce the Perfection Gap Factor (PGF) to characterize task-to-task transfer and leverage task interactions to identify effective proxy datasets.

A training-free, lightweight frame selection algorithm for long-video understanding. We model a video as a differentiable trajectory in visual latent space and use a Taylor expansion to predict future features; frames with large residuals ("temporal surprises") are selected as keyframes. Adds only 0.02× overhead while improving VQA accuracy by up to +12.5 points.
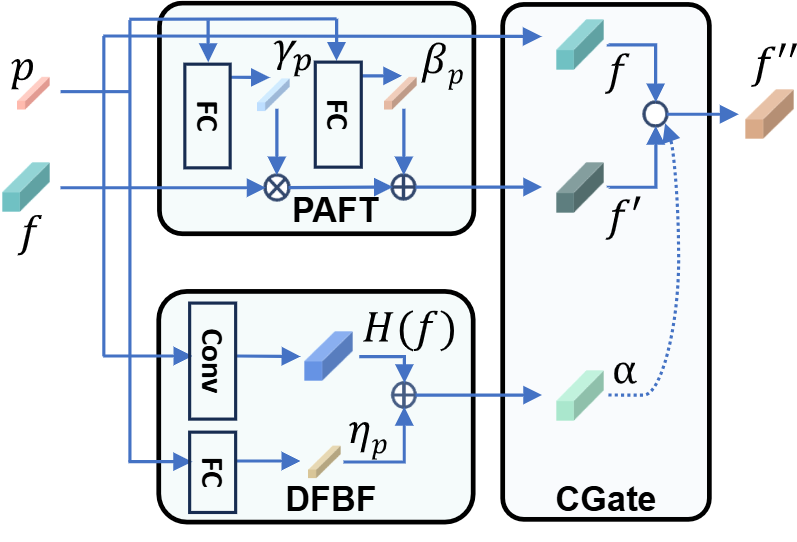
We present the first comprehensive dataset for MSICS cataract surgery tool segmentation and introduce ToolSeg, a phase-informed segmentation method that leverages surgical phases to enhance tool segmentation accuracy.
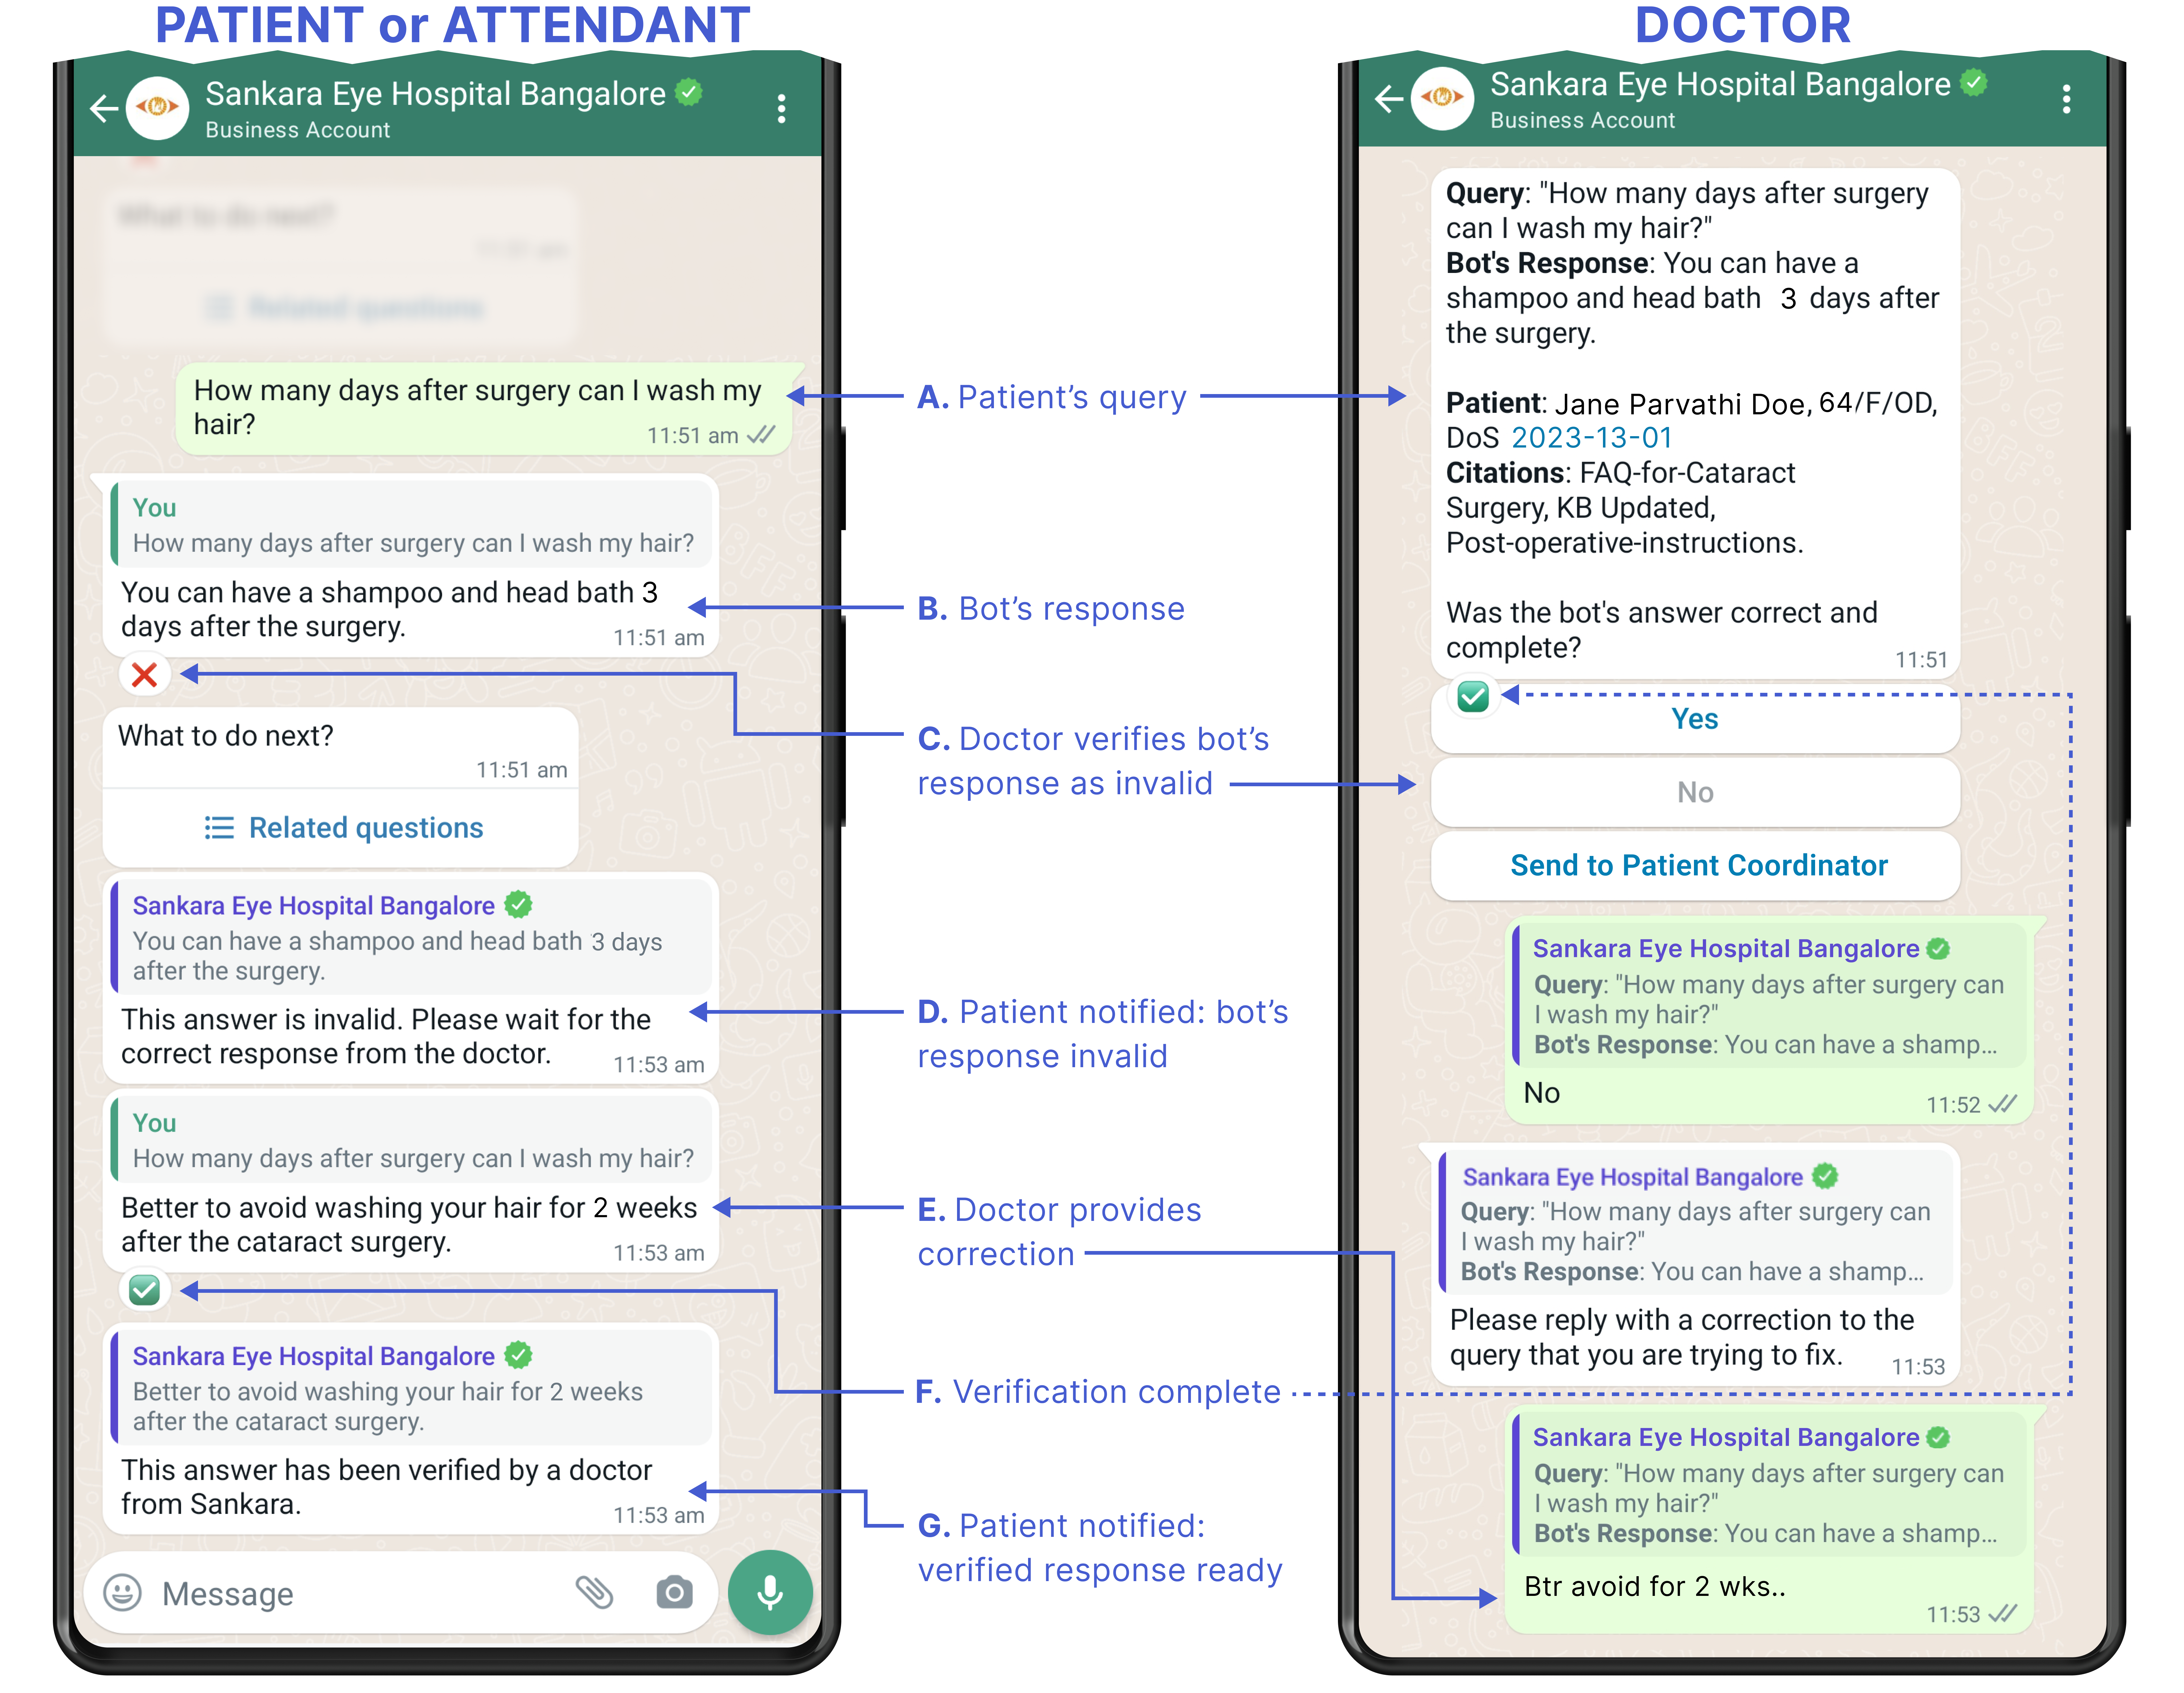
We developed CataractBot, an LLM-powered chatbot answering cataract surgery questions via a curated knowledge base with expert-verified responses, supporting multimodal and multilingual inputs.